Trustworthy AI data comes from five practices: clear guidelines, real domain expertise, measured agreement between annotators, documented quality checks, and honest records of where the data came from. This article explains each one and lists questions to ask any data partner.
An AI model can only be as reliable as the data it learned from. In everyday applications, a mislabeled image is a small nuisance. In scientific and medical AI, it can quietly distort a research result, weaken a diagnostic model, or make an experiment impossible to reproduce. That is why “good enough” data is not good enough in these fields, and why the word trustworthy deserves a precise meaning.
This article explains what makes AI data trustworthy in scientific and medical settings, what to look for in your own datasets, and which questions to ask any data partner before you start.
Why the bar is higher in science and medicine
Three things make scientific and medical data different from general-purpose data.
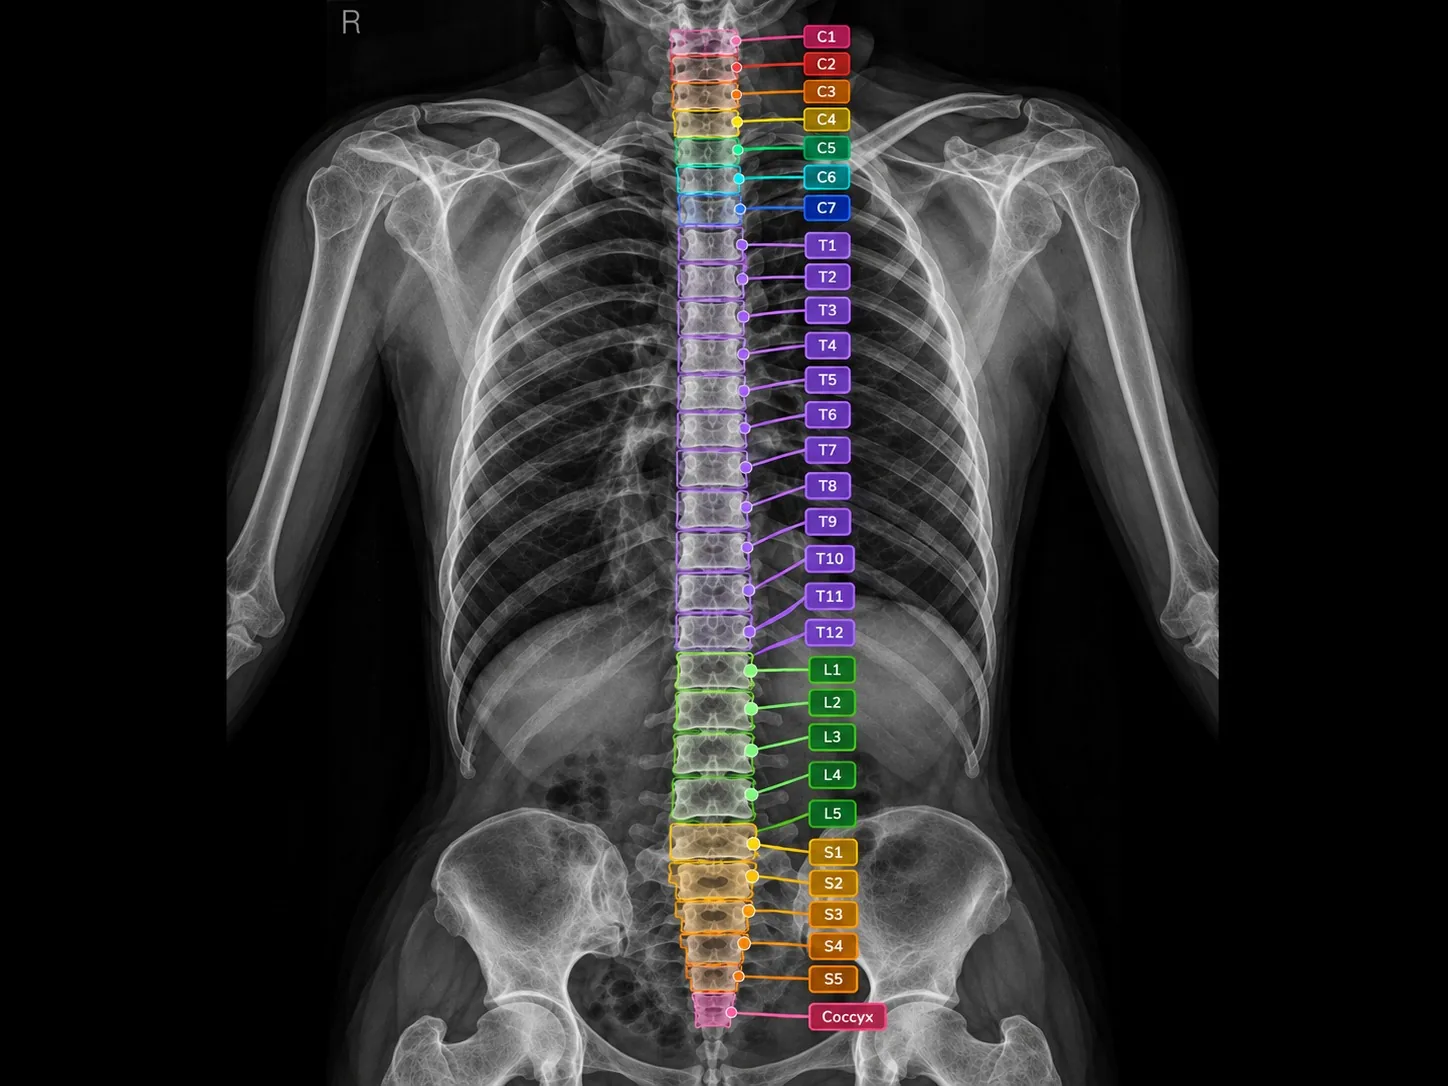
Labeling needs judgment, not just attention. Deciding where a tissue boundary sits on a stained slide, whether a cell is damaged or simply oriented differently, or whether a leaf shows early disease or a nutrient deficiency takes domain knowledge. Two careful people without that background can look at the same image and reasonably disagree.
Errors are silent. A model does not flag bad labels. It learns from them, and the mistakes show up later as unexplained performance gaps, often after significant time and money have been spent.
The consequences travel further. Data may feed published research, validation studies, or workflows that are eventually reviewed by regulators. In those settings you need to show how the data was produced, not just hand over a file.
What makes AI data trustworthy
Trustworthy data is not a feeling. It is the result of specific practices that can be inspected. Five matter most.
1. A clear specification before labeling starts
Most quality problems begin with vague instructions. A good specification defines each class, shows examples and counter-examples, and says what to do with ambiguous cases. Writing the hard cases into the guidelines up front, rather than leaving each annotator to guess, is the single cheapest way to improve consistency.
2. Domain expertise in the loop
Specialized data needs people who understand the terminology, the context, and the edge cases of the field. That may mean expert reviewers checking the work, or your own specialists helping define and verify the hard calls. Expertise matters most where the data is ambiguous, which is exactly where models are most likely to fail.
3. Measured agreement, not assumed agreement
If several annotators label the same sample, how often do they agree? Inter-annotator agreement turns “we think the labels are consistent” into something you can measure. Disagreement is also useful information: it points to unclear definitions, genuinely difficult cases, or guidelines that need updating. When annotators disagree, a defined process, such as a senior reviewer making the final call and the guidelines being updated afterwards, keeps the dataset consistent.
4. Layered, documented quality assurance
Quality should be built into the process rather than checked once at the end. Structured review, validation, discrepancy resolution, and tracking of rework all help, and so does keeping a record of what was found and fixed. If nobody can show you the review outcomes, you cannot really know the quality.
5. Provenance and honest documentation
Trustworthy data comes with its history: where it came from, who labeled it, which version of the guidelines was used, and what its known limitations are. A dataset that is open about what it does not cover is more useful than one that claims to cover everything.
Where AI-assisted annotation fits
AI-assisted tools can speed up labeling by producing a first pass that people then correct. That can be valuable, but only if the output is never treated as ground truth. A human should review every AI-generated label, and the process should be clear about which parts were machine-assisted. It also has to respect the customer’s rules: if a contract prohibits external AI tools on the data, they should not be used.
Questions to ask any data partner
Before starting a project, ask:
- Who reviews specialized data, and what is their background?
- How are ambiguous cases handled? Is there a written rule, and who decides when annotators disagree?
- How is quality measured, and can you see the evidence rather than just a claimed accuracy number?
- Can you run a small pilot on your own data and guidelines before committing to the full project?
- What happens to your data? Is it used to train any model without your written permission, and what is returned or deleted at the end?
- Which formats are delivered, and do they fit your pipeline?
Common mistakes to avoid
- Measuring volume instead of quality. A large dataset with inconsistent labels can be worse than a smaller, carefully reviewed one.
- Skipping the pilot. A small sample reviewed against your guidelines catches misunderstandings while they are still cheap to fix.
- Letting guidelines drift silently. If definitions change mid-project, earlier labels may no longer match later ones unless the change is tracked and applied consistently.
- Leaving out the limitations. Every dataset has gaps. Stating them protects both you and the people who use the model later.
The takeaway
Trustworthy AI data comes from clear specifications, real domain expertise, measured agreement, documented quality checks, and honest records of where the data came from and what it cannot do. None of these are exotic, but together they are what separate data you can build on from data you merely hope is right.
We begin by annotating a small sample to your guidelines, so you can review the results and agree on the approach before scaling up.